How to Choose a Process Monitor Based on Response Time and Alarm Accuracy


Selecting the right process monitor is rarely about choosing the device with the fastest published specification. For technical evaluators, the harder question is whether a monitor can detect a real process deviation early enough to matter, while avoiding false or ambiguous alarms that operators stop trusting. In practice, response time and alarm accuracy are tightly linked to process dynamics, sensor behavior, signal conditioning, control architecture, and even human factors in the control room.
A poor fit creates familiar problems: a monitor that reacts quickly in the datasheet but slowly in the field, alarms that chatter during normal disturbances, missed excursions during fast transients, or an apparently “stable” system that is only stable because it has been over-filtered. The right choice depends less on brand claims and more on how the instrument performs within the real process context.
This is why evaluation should start with a decision framework, not a product list. A process monitor should be judged by how reliably it turns changing process conditions into actionable information under actual plant constraints.
Why response time is often misunderstood
Many buyers treat response time as a single number. It is not. In most industrial monitoring applications, total effective response is the sum of several delays:
- sensor response time;
- sampling interval;
- signal filtering or damping;
- transmitter or analyzer computation time;
- communication update cycle;
- controller or SCADA scan rate;
- alarm deadband, delay, or voting logic.
This means a process monitor with a 100 ms internal update rate may still produce an alarm several seconds late once installed in a distributed control environment. Technical evaluators should therefore avoid comparing vendor specifications in isolation. A “fast” monitor in a lab test may be functionally slow in a plant with multiplexed inputs, slow network polling, or aggressive noise suppression.
The key question is not “What is the nominal response time?” but “What is the maximum acceptable time from process deviation to trusted alarm at the operator or shutdown layer?” That number differs sharply by application. A boiler flame instability issue, compressor surge precursor, toxic gas release, or rapid exothermic reaction does not tolerate the same alarm latency as level trend monitoring in a storage tank.
Alarm accuracy is not just about correctness
Alarm accuracy is often interpreted too narrowly as whether the alarm eventually indicates a real event. In plant reality, accuracy has at least four dimensions:
- Detection accuracy: does the monitor identify true abnormal conditions?
- Timing accuracy: does it alarm early enough to support intervention?
- Stability: does it avoid nuisance, chattering, or repeated alarms?
- Context accuracy: does the alarm logic reflect the process state, operating mode, and actual risk?
A monitor that detects all real events but generates frequent nuisance alarms is operationally inaccurate in a meaningful sense. Once operators learn that alarms are unreliable, response discipline degrades. In regulated sectors and high-hazard facilities, this is not a minor usability issue; it becomes a process safety concern.
For this reason, technical evaluation should include not only alarm threshold performance but also alarm management behavior: deadband configuration, persistence timers, suppression during startup or cleaning cycles, latching behavior, and event logging resolution.
Start with process dynamics, not the monitor category
Before comparing suppliers or architectures, define the process event you need to catch. This sounds obvious, but it is where many selection exercises go off track. A process monitor should be matched to the speed and nature of the abnormal condition, not to the generic variable being measured.
Consider three very different use cases:
- Fast transient protection: pressure spikes, thermal runaway indicators, vibration excursions, current anomalies.
- Continuous quality or compliance monitoring: pH drift, dissolved oxygen shifts, stack emissions, conductivity, moisture.
- Condition change confirmation: filter blockage, pump cavitation onset, heat exchanger fouling trend, tank overfill risk.
Each case requires a different balance. Fast transient monitoring prioritizes minimal total latency and high signal integrity. Compliance-oriented monitoring may tolerate slower response but demands strong stability, traceability, and calibration confidence. Condition monitoring often benefits more from robust trend discrimination than from raw speed.
If the event profile is unclear, the resulting procurement often defaults to over-specified speed or over-smoothed stability—both expensive mistakes.
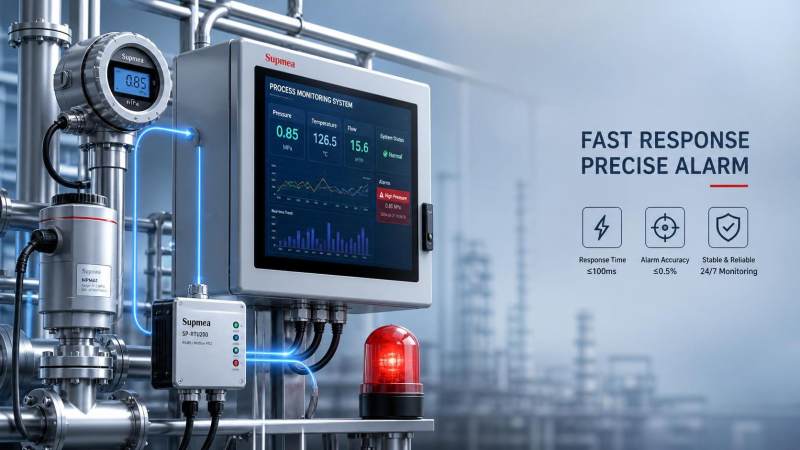
What to test when vendors claim “fast” and “accurate”
Published brochures rarely provide enough detail for a serious decision. Technical evaluators should ask for performance evidence under conditions resembling the intended application. The most useful questions are practical:
- What is the sensor T90 or T63 response under the actual medium, temperature, and pressure range?
- How much configurable filtering is applied by default?
- What is the raw input update rate versus displayed update rate versus alarm evaluation cycle?
- Are alarm thresholds evaluated on every sample or on averaged values?
- How does the monitor behave during signal dropout, drift, spike noise, or communication interruption?
- Can time stamping be synchronized across systems?
- What event log granularity is available for root-cause review?
Where possible, request a cause-and-effect test, not just a bench demo. For instance, inject a controlled step change, ramp change, and noisy fluctuation into the signal path. Observe not only whether the monitor alarms, but when, how repeatedly, and with what operator-facing information.
This matters especially when comparing analyzer-based monitors with simpler transmitter-based devices. Analyzer systems may offer richer diagnostics and better discrimination but can introduce sample transport lag, conditioning delays, and maintenance dependencies that materially affect usable response time.
Filtering, damping, and the trade-off nobody escapes
Almost every process monitor must manage noise. The problem is that noise suppression often improves apparent alarm accuracy while worsening detection latency. This is where many field disappointments come from.
If a signal is heavily damped, nuisance alarms may disappear during commissioning, which looks like success. But the same damping may delay legitimate alarms beyond the intervention window. On the other hand, if filtering is too light, the monitor may react to turbulence, electrical noise, pulsation, or process cycling rather than to meaningful deviation.
Technical evaluators should insist on understanding:
- whether filtering is analog, digital, or both;
- whether different filters apply to display, control output, and alarm logic;
- whether adaptive filtering or rate-of-change logic is available;
- whether deadband and time delay can be tuned independently by alarm priority.
In many applications, the best answer is not “more filtering” but better alarm design. A high alarm, high-high alarm, and rate-of-change alarm may collectively perform better than one heavily damped threshold alarm. This is especially true in processes with cyclical behavior or naturally variable load conditions.
Integration quality can erase instrument quality
A capable process monitor can underperform once integrated into a plant architecture that was not designed for timely alarming. Technical evaluators should examine the entire signal chain, including protocol choice, controller scan times, historian polling, and alarm annunciation path.
Common failure points include:
- slow Modbus polling on multi-drop networks;
- non-deterministic Ethernet traffic in mixed-use environments;
- SCADA refresh rates that are slower than device updates;
- alarm evaluation performed in a higher-level system instead of at the edge;
- loss of diagnostic detail when mapping smart-device data into legacy systems.
For fast-risk processes, the monitor may need local alarm processing or direct hardwired outputs rather than relying solely on supervisory software. For less time-critical applications, richer digital integration may be preferable because it supports diagnostics, audit trails, and remote maintenance. The correct choice depends on whether the operational priority is speed, contextual intelligence, or a balance of both.
Accuracy depends on maintenance as much as design
When alarm accuracy degrades over time, the cause is often not poor alarm logic but degraded measurement quality. Drift, fouling, contamination, aging sensors, blocked impulse lines, sample conditioning issues, and missed calibration intervals all turn a good monitor into a misleading one.
For this reason, selection should include maintainability criteria:
- calibration interval and method;
- diagnostic coverage for drift or sensor health;
- availability of self-check or validation routines;
- accessibility for service in hazardous or hard-to-reach areas;
- spare parts availability and lead times;
- documentation quality for troubleshooting and proof testing.
In sectors such as pharmaceuticals, energy, chemicals, and environmental monitoring, documentation and traceability may matter nearly as much as response speed. If alarm behavior affects compliance, incident investigation, or product release decisions, data integrity becomes part of the accuracy discussion.
Application-specific red flags during evaluation
Several warning signs tend to appear across projects:
The monitor is chosen based on variable type alone. Two temperature monitors may be entirely unsuitable for the same duty if one is intended for slow thermal profiling and the other for rapid overtemperature protection.
Alarm setpoints are copied from a previous site. Thresholds that worked in one process may become noisy or dangerously late in another because of different line volume, control valve behavior, residence time, or operator response capability.
Bench performance is accepted as field performance. Real installations add tubing lengths, process lag, EMI exposure, communication delays, and maintenance realities.
The team optimizes for false alarm reduction only. Reducing nuisance alarms is valuable, but not if it suppresses weak early-warning signals that would have enabled intervention.
Cybersecurity and firmware governance are ignored. Increasingly connected monitoring systems require patch control, user access management, and version traceability. These factors can affect uptime and alarm trustworthiness, especially in multinational industrial environments.
A practical selection logic for technical evaluators
In most cases, a sound evaluation can be framed around five decision questions.
How fast does the abnormal event develop?
Map the time from deviation onset to required operator or automatic action. This defines your latency budget.
What signal quality problems are intrinsic to the process?
Identify expected noise, pulsation, drift, contamination, cycling, and startup/shutdown behavior. This shapes the alarm strategy more than the nominal instrument class does.
Where should alarm intelligence reside?
At the sensor edge, transmitter, local controller, DCS, or supervisory platform. The answer changes both speed and resilience.
How will the monitor be maintained and validated?
A technically elegant device with weak serviceability may deliver poor alarm accuracy after a year in operation.
What is the consequence of being late versus being wrong?
In some processes, a nuisance alarm is tolerable but a missed event is not. In others, alarm overload creates major operational loss. The weighting must be explicit.
What a strong procurement decision looks like
The best process monitor selection is rarely the one with the most extreme specification. It is the one whose response behavior, alarm logic, integration pathway, and maintenance profile remain credible after the process realities are accounted for.
For technical evaluators, that usually means moving beyond catalog comparison and asking for evidence under representative conditions. It also means treating response time and alarm accuracy as system-level outcomes rather than device-level claims. Once that shift is made, the choice becomes clearer: not which monitor is theoretically fastest, but which one produces timely, trusted, and operationally useful alarms in the plant you actually have.
That distinction is where better procurement decisions are made—and where monitoring performance starts to support real risk reduction instead of just satisfying a specification sheet.
Recommended for You
 How to prevent false alarms in power plant instrumentationPower plant instrumentation guide: prevent false alarms with reliable signal checks, smarter alarm settings, mode-based control, and actionable operator responses.
 How fixed gas detectors help prevent leaks in enclosed workspacesFixed gas detectors provide continuous leak monitoring in enclosed workspaces, enabling faster alarms, safer responses, and stronger protection for people and processes.
 How industrial gas analysis helps detect process contamination earlyIndustrial Gas Analysis helps detect oxygen, moisture, and hydrocarbon contamination early, enabling faster fault isolation, safer operations, and stronger process control.
 What drives environmental compliance continuous monitoring setup cost?Environmental compliance continuous monitoring setup cost: uncover hidden expenses, compare bids accurately, and build a reliable, audit-ready system.
 How to select gas analysis equipment for continuous emissions monitoringGas analysis equipment selection guide for reliable continuous emissions monitoring—compare technologies, sampling, calibration, compliance, and maintenance needs.
 What detection limit is needed for NH3 environmental monitoring?High accuracy NH3 analyzer for environmental monitoring: learn how to set the right detection limit, improve sampling reliability, and make defensible decisions.
 How to select a NOX analyzer for power plant emissions complianceNOX analyzer for power plant emissions: learn how to select a compliant, reliable CEMS solution with the right range, sample handling, calibration, and data integrity.
 How to evaluate a laser gas analyzer manufacturer in GermanyLaser gas analyzer manufacturer in Germany: compare accuracy, sample handling, interference control, calibration, and service to select a reliable solution.
 How does a flue gas analyzer maintain accuracy in wet stack gas?Flue gas analyzer accuracy in wet stack gas depends on heated sampling, moisture correction, reliable sensors, and calibration. Explore key selection tips.
 What makes equipment suitable for a hazardous environment?Hazardous Environment equipment selection explained: certification, ignition control, materials, installation, and maintenance for safer operations.
 How Can Fugitive Emission Monitoring Results Be Validated?How to validate fugitive emission monitoring results: learn calibration, field documentation, data-quality checks, and compliance comparisons for credible, decision-ready reports.
 Do Stack Testing Instruments Need Heated Sample Lines?Do stack testing instruments need heated sample lines? Learn when heating protects sample integrity, prevents condensation, and improves reliable emissions measurements.
 What Are the Risks of Using Low-Cost Electrochemical Gas Analyzers?What are the risks of using low-cost electrochemical gas analyzers? Explore calibration drift, cross-sensitivity, safety, and compliance concerns before you buy.
 How Long Does It Take to Integrate a Custom Emission Monitoring Solution?How long does it take to integrate a custom emission monitoring solution? Explore timelines, site readiness, data integration, and validation factors.
 Is Industrial Safety Monitoring the Same as Emission Monitoring?is industrial safety monitoring the same as emission monitoring? Learn the key differences in purpose, alarms, compliance, and instrument selection for safer operations.
 What Monthly Maintenance Does a Wireless Measurement Node Need?What maintenance does a wireless measurement node need monthly? Explore practical checks for battery health, signal quality, sensor accuracy, enclosures, and reliable data.
 Can Measurement and Control Systems Handle Corrosive Flue Gas?Can measurement and control systems handle corrosive flue gas? Discover proven design strategies for reliable sensing, sampling, materials, and maintenance.
 How Can Data Logging Instruments Pass an Environmental Audit?Learn how to ensure data logging instruments pass environmental audit with proven calibration, data integrity, alarm control, and traceable compliance records.
 What Are the Common Pitfalls of Integrating Multiple Gas Analyzers?What are common pitfalls when integrating multiple gas analyzers? Discover how sampling, timing, calibration, and data integration risks affect reliable decisions.
 Is Predictive Analytics for Emission Control Useful or Just Hype?Is predictive analytics useful for emission control or just hype? Discover how reliable data, CEMS, and practical pilots can reduce risk and support compliance.
 How to select a hydrogen analyzer for petrochemical process safetyHydrogen analyzer for petrochemical industry selection guide: compare technologies, sample systems, response time, and safety certifications for reliable process protection.
 When does a thermal conductivity detector outperform an FID?Thermal conductivity detector vs. FID: discover when TCD is the smarter choice for permanent gases, bulk analysis, non-destructive detection, and reliable GC method design.
 What certification should you verify before buying an IECEx analyzer?IECEx analyzer buyers: verify the Certificate of Conformity, Ex marking, special conditions, and exact configuration before purchase. Avoid costly compliance risks.
 How oxygen analysis helps prevent incomplete combustionOxygen analysis helps prevent incomplete combustion by optimizing air-to-fuel balance, reducing fuel waste, improving burner safety, and supporting emissions control.
 How to size an industrial gas system for stable peak demandIndustrial gas system sizing guide for stable peak demand. Learn how to assess flow, pressure drop, buffer storage, purity, redundancy, and commissioning for reliable production.
 How to choose a process sensor for high-temperature applicationsProcess sensor selection for high-temperature applications: compare thermal limits, materials, accuracy, installation, and maintenance to secure reliable control data.
 When does continuous analysis improve industrial process control?Continuous analysis improves industrial process control with timely composition data that supports faster decisions, higher quality, safer operations, and less waste.
 How to choose emission control systems for variable industrial loadsEmission Control solutions for variable industrial loads: learn how to match technology, controls, monitoring, and lifecycle costs for reliable compliance.
 How continuous emissions monitoring supports reliable emission reductionEmission Reduction relies on reliable continuous emissions monitoring. Discover how accurate data, calibration, and process insights support compliance and smarter control.
 When does it make sense to automate a production line?Production Line automation makes sense when processes are stable, measurable, and repeatable. Learn the key signals, risks, and ROI triggers before you invest.
 What accuracy should a monitoring device deliver in power quality applicationsMonitoring Device accuracy in power quality applications affects compliance, troubleshooting, and decision confidence. Learn what specs, standards, and installation factors truly matter.
 When does stack equipment make sense for small-scale production?Stack equipment can be a smart upgrade for small-scale production when space is tight and output is steady. Learn when it boosts efficiency—and when it adds costly complexity.




Search Categories
Search Categories
- Smart Meters & Power Quality
- Transformer Gas Analyzers
- BESS Thermal Runaway Detectors
- Energy, Power & Smart Grid Monitoring
- Optical Profilers & CMM
- Ultrasonic & X-Ray NDT
- Calibration Standards
- Precision Metrology & NDT
- Water Quality Analyzers
- CEMS & VOCs Monitors
- Price Trends
- Import & Export Updates
- Market Trends
- Industry News
- Industry Insights
Latest Article
- How to prevent false alarms in power plant instrumentationPower plant instrumentation guide: prevent false alarms with reliable signal checks, smarter alarm settings, mode-based control, and actionable operator responses.Posted by:
- How fixed gas detectors help prevent leaks in enclosed workspacesFixed gas detectors provide continuous leak monitoring in enclosed workspaces, enabling faster alarms, safer responses, and stronger protection for people and processes.Posted by:
- How industrial gas analysis helps detect process contamination earlyIndustrial Gas Analysis helps detect oxygen, moisture, and hydrocarbon contamination early, enabling faster fault isolation, safer operations, and stronger process control.Posted by:
Please give us a message