
How to prevent false alarms in power plant instrumentation


False alarms in a power plant are more than an annoyance. A single spurious high-pressure, low-level, flame-failure, vibration, or temperature alarm can interrupt an operator’s attention at the wrong moment. When alarms repeat without a real process consequence, control-room staff may begin to acknowledge them automatically, delay investigation, or work around them informally. That weakens the alarm system precisely when a genuine abnormal condition needs a rapid response.
Most nuisance alarms are preventable, but prevention rarely comes from one adjustment in the control system. Reliable power plant instrumentation depends on a chain of decisions: the measurement must represent the process, the signal path must remain healthy, the alarm must suit the operating mode, and the operator must be given a response that is both clear and achievable. A practical program starts by separating bad signals from poorly designed alarms, because the corrective actions are very different.
Start by determining whether the alarm reflects the process
An alarm can be technically valid while still being operationally useless. A boiler drum level may move briefly during a load change. Condensate pressure may fluctuate as a standby pump starts. Stack-gas readings may shift during a transition between fuels or operating conditions. If these changes are expected and remain within the safe operating envelope, alarming on every short excursion creates noise rather than protection.
The first review should therefore compare three things: the displayed value, the actual process condition, and the alarm event history. Operators and instrument technicians should ask whether the indication changes plausibly relative to related measurements. For example, a sudden level change with no corresponding change in flow, pressure, pump status, or vessel conditions deserves suspicion. A temperature signal that jumps sharply while nearby points remain stable may be an instrument or connection problem rather than a thermal event.
Trend displays are often more informative than a single alarm record. Look for a repeatable pattern:
- Does the alarm occur at a particular load, ambient condition, or time after equipment starts?
- Does it appear during routine sootblowing, pump changeover, turbine maneuvering, or control-valve movement?
- Is the signal oscillating around one threshold, or does it make abrupt, implausible steps?
- Do redundant channels disagree, and if so, does one channel consistently deviate?
- Does the alarm clear on its own without any process action, then return under the same operating condition?
Those questions prevent a common mistake: treating every recurring alarm as an alarm-configuration problem. A poorly installed impulse line, a fouled sensing port, intermittent transmitter power, water ingress in a junction box, an unstable thermocouple connection, or electrical interference can all produce a control-room symptom that looks like a threshold problem. Changing limits before investigating signal integrity can hide the fault and create a larger blind spot.
For critical measurements, confirmation should rely on an independent indication where one is available. That may be another transmitter, a local gauge, a field inspection, a calculated process balance, or a related equipment variable. The objective is not to force all signals to agree. It is to establish whether the alarm reflects a credible change in the equipment being protected.
Fix the measurement path before tuning the alarm
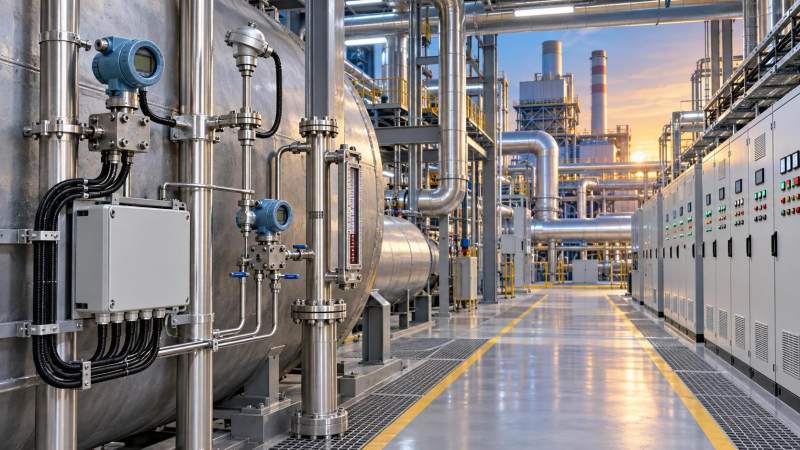
Many false alarms originate in the field layer of power plant instrumentation. The control system only evaluates the value it receives. If the primary element, sensing line, transmitter, wiring, or input channel is unstable, even a well-designed alarm will behave badly.
Pressure and differential-pressure measurements deserve close attention in steam-water systems. Plugged impulse lines, unequal leg temperatures, leaking fittings, poor heat tracing, or condensate accumulation can distort a reading. Level applications are especially sensitive because a differential-pressure transmitter can be affected by density changes, wet-leg condition, reference-leg condition, and installation geometry. A recurring drum-level or feedwater-level alarm should be assessed in the context of its measurement arrangement, not calibrated blindly at the transmitter terminals.
Temperature measurements have their own failure modes. Loose terminal connections, damaged extension cable, incorrect compensation arrangements, poor thermowell contact, and sensor drift can create transient or biased readings. A thermocouple circuit may appear healthy during a static check yet fail when vibration, heat, or moisture affects a marginal connection. Resistance temperature devices can develop intermittent faults that are difficult to identify unless technicians review the signal during the conditions that trigger the alarm.
Flow and analytical measurements often create nuisance alarms when the process interface is neglected. Differential-pressure flow elements can be affected by wetting, plugging, and poor impulse-line maintenance. Conductivity, pH, dissolved oxygen, and gas-analysis systems can be influenced by sample conditioning, contaminated probes, calibration issues, inadequate sample flow, or delayed transport from the process to the analyzer. In those cases, a stable control-room value may still be misleading, while an unstable value may accurately reveal a sample-system problem rather than a process excursion.
A useful maintenance response is to record the alarm condition before disturbing the equipment. Capture the trend, operating mode, relevant equipment statuses, field value, controller output, and any diagnostic messages. Then inspect the likely failure path systematically. A calibration check remains important, but calibration alone does not prove that the installed measurement will remain reliable under pressure, temperature, vibration, electrical noise, or changing process conditions.
Set alarm limits around operating decisions, not normal variation
An alarm should tell an operator that a defined action is needed. If no action is required, the point may need an event log, an advisory display, or a different alarm strategy rather than a conventional audible alarm.
Alarm setpoints are often inherited from commissioning documents, copied between similar units, or retained after changes in fuel, dispatch patterns, control philosophy, or equipment condition. That does not make them wrong, but it does mean they should be tested against present operating reality. A threshold placed too close to a normal control band will chatter whenever the process cycles. A threshold placed too far from the operating limit may provide little time to respond.
For each recurring alarm, establish four practical boundaries: the normal operating range, the control-system operating range, the point at which operator intervention should begin, and the equipment or safety limit that must not be crossed. These ranges are not always the same. A control loop may legitimately move a variable through a range that should not generate alarms, while a separate high-high or low-low protection function may need to remain tightly controlled.
Deadband and delay are useful tools, but they are frequently misapplied. A deadband prevents repeated entering and leaving of an alarm state when the variable hovers around the threshold. A delay requires the condition to persist before annunciation. Both can reduce noise from short disturbances. Neither should be used to conceal a fast-developing hazard.
The decision depends on the process response time and the consequence of delay. A slowly moving cooling-water temperature may tolerate a modest persistence requirement if short fluctuations have no operational consequence. A protection-related flame, turbine, generator, boiler, or high-energy steam condition requires a much more conservative review. In those applications, filtering and delay must be assessed with the responsible engineering and safety functions, not added during routine troubleshooting.
Manage alarms by operating mode
Plants do not operate in one steady state. Startup, shutdown, cold standby, hot standby, load ramping, equipment testing, unit trips, bypass operation, and maintenance all create conditions that differ from normal generation. An alarm that is useful at full load may be irrelevant or unavoidable while equipment is out of service. Leaving every alarm active in every mode often produces predictable alarm floods.
Mode-based alarm management can reduce that burden when it is implemented with discipline. A low-flow alarm on an isolated line may be suppressed when the line is positively confirmed out of service. A pump discharge-pressure alarm may need different treatment while the pump is unavailable, starting, or running. Some alarms can be shelved temporarily under defined operating controls; others must remain active regardless of mode because they protect personnel, equipment, or a safety function.
The distinction matters. Suppression should be tied to a verified plant state, visible to the operator, and automatically removed when the relevant state changes. Permanent bypasses, undocumented overrides, and broad alarm inhibits create hidden exposure. A plant may appear quieter while its ability to detect a real fault has been reduced.
Every alarm that can be suppressed should have clear ownership: who authorizes it, how long it can remain suppressed, how its status is displayed, and how it is reviewed at shift handover. Operators should never have to infer whether a missing alarm is a healthy condition or a disabled one.
Reduce alarm floods by finding the initiating event
When one equipment upset creates dozens of alarms, the solution is rarely to delete dozens of points. The better approach is to identify the initiating event and decide which later alarms add meaningful information. A feedwater pump trip, for example, may lead to changes in discharge pressure, flow, drum level, controller output, valve position, and turbine or boiler load. Some of these indications are essential for diagnosis; others only repeat the same message in a more confusing form.
Alarm rationalization should ask a simple operational question for each point: when this alarm occurs, what is the operator expected to do, and how much time is available? If the response is “nothing beyond responding to the first alarm,” the point may be better treated as an event, a lower-priority advisory, or a consequence alarm with carefully designed behavior.
Priority should reflect consequence and response urgency, not the importance of the instrument in isolation. A measurement can be essential to performance monitoring but still not justify a high-priority alarm. Conversely, an alarm with a narrow response window may need clear annunciation even if it occurs infrequently. Excessive high-priority alarms dilute the purpose of prioritization and make it harder for an operator to locate the first actionable signal during a disturbance.
Give operators a response they can execute
A well-configured alarm still fails operationally if its meaning is vague. “High temperature” is not enough when several components have similar tags, different limits, and different consequences. Alarm guidance should identify the affected equipment, likely causes, confirmation steps, immediate action, escalation point, and conditions for return to normal operation.
This does not require turning every alarm into a long procedure on the screen. Short, consistent guidance is often sufficient, especially when it points to the correct operating procedure. What matters is that the alarm tells the operator whether to verify a measurement, adjust a control, start standby equipment, reduce load, isolate a system, or call for field support.
Shift handover is a useful control point. Standing alarms, disabled points, repeated chattering alarms, and instruments awaiting maintenance should be explicitly discussed. An alarm that has become familiar over several shifts can be particularly dangerous because its abnormal status has been normalized without being resolved.
Build a repeatable review cycle
False-alarm reduction works best as an operating discipline rather than a one-time cleanup. Review recurring alarms after meaningful events, including load changes, starts, trips, maintenance outages, and control-system modifications. Preserve alarm-history data and examine the highest-frequency alarms, the longest-standing alarms, repeat alarms from one tag, and alarm floods around a common timestamp.
Changes should be controlled and traceable. Before modifying a setpoint, delay, priority, suppression rule, or signal filter, document the reason, the process condition being addressed, the expected effect, and any limit on applicability. After the change, review whether the nuisance behavior actually declined and whether the operator still receives timely warning under credible abnormal conditions.
The practical aim is not an alarm-free control room. Power generation equipment needs alarms because process conditions, equipment health, and protective margins can change quickly. The target is a control room where an alarm is credible, relevant to the current operating state, and linked to a response. When power plant instrumentation provides that level of signal quality and alarm discipline, operators can direct attention to developing hazards instead of sorting through avoidable noise.
Recommended for You
 How to prevent false alarms in power plant instrumentationPower plant instrumentation guide: prevent false alarms with reliable signal checks, smarter alarm settings, mode-based control, and actionable operator responses.
 How fixed gas detectors help prevent leaks in enclosed workspacesFixed gas detectors provide continuous leak monitoring in enclosed workspaces, enabling faster alarms, safer responses, and stronger protection for people and processes.
 How industrial gas analysis helps detect process contamination earlyIndustrial Gas Analysis helps detect oxygen, moisture, and hydrocarbon contamination early, enabling faster fault isolation, safer operations, and stronger process control.
 What drives environmental compliance continuous monitoring setup cost?Environmental compliance continuous monitoring setup cost: uncover hidden expenses, compare bids accurately, and build a reliable, audit-ready system.
 How to select gas analysis equipment for continuous emissions monitoringGas analysis equipment selection guide for reliable continuous emissions monitoring—compare technologies, sampling, calibration, compliance, and maintenance needs.
 What detection limit is needed for NH3 environmental monitoring?High accuracy NH3 analyzer for environmental monitoring: learn how to set the right detection limit, improve sampling reliability, and make defensible decisions.
 How to select a NOX analyzer for power plant emissions complianceNOX analyzer for power plant emissions: learn how to select a compliant, reliable CEMS solution with the right range, sample handling, calibration, and data integrity.
 How to evaluate a laser gas analyzer manufacturer in GermanyLaser gas analyzer manufacturer in Germany: compare accuracy, sample handling, interference control, calibration, and service to select a reliable solution.
 How does a flue gas analyzer maintain accuracy in wet stack gas?Flue gas analyzer accuracy in wet stack gas depends on heated sampling, moisture correction, reliable sensors, and calibration. Explore key selection tips.
 What makes equipment suitable for a hazardous environment?Hazardous Environment equipment selection explained: certification, ignition control, materials, installation, and maintenance for safer operations.
 How Can Fugitive Emission Monitoring Results Be Validated?How to validate fugitive emission monitoring results: learn calibration, field documentation, data-quality checks, and compliance comparisons for credible, decision-ready reports.
 Do Stack Testing Instruments Need Heated Sample Lines?Do stack testing instruments need heated sample lines? Learn when heating protects sample integrity, prevents condensation, and improves reliable emissions measurements.
 What Are the Risks of Using Low-Cost Electrochemical Gas Analyzers?What are the risks of using low-cost electrochemical gas analyzers? Explore calibration drift, cross-sensitivity, safety, and compliance concerns before you buy.
 How Long Does It Take to Integrate a Custom Emission Monitoring Solution?How long does it take to integrate a custom emission monitoring solution? Explore timelines, site readiness, data integration, and validation factors.
 Is Industrial Safety Monitoring the Same as Emission Monitoring?is industrial safety monitoring the same as emission monitoring? Learn the key differences in purpose, alarms, compliance, and instrument selection for safer operations.
 What Monthly Maintenance Does a Wireless Measurement Node Need?What maintenance does a wireless measurement node need monthly? Explore practical checks for battery health, signal quality, sensor accuracy, enclosures, and reliable data.
 Can Measurement and Control Systems Handle Corrosive Flue Gas?Can measurement and control systems handle corrosive flue gas? Discover proven design strategies for reliable sensing, sampling, materials, and maintenance.
 How Can Data Logging Instruments Pass an Environmental Audit?Learn how to ensure data logging instruments pass environmental audit with proven calibration, data integrity, alarm control, and traceable compliance records.
 What Are the Common Pitfalls of Integrating Multiple Gas Analyzers?What are common pitfalls when integrating multiple gas analyzers? Discover how sampling, timing, calibration, and data integration risks affect reliable decisions.
 Is Predictive Analytics for Emission Control Useful or Just Hype?Is predictive analytics useful for emission control or just hype? Discover how reliable data, CEMS, and practical pilots can reduce risk and support compliance.
 How to select a hydrogen analyzer for petrochemical process safetyHydrogen analyzer for petrochemical industry selection guide: compare technologies, sample systems, response time, and safety certifications for reliable process protection.
 When does a thermal conductivity detector outperform an FID?Thermal conductivity detector vs. FID: discover when TCD is the smarter choice for permanent gases, bulk analysis, non-destructive detection, and reliable GC method design.
 What certification should you verify before buying an IECEx analyzer?IECEx analyzer buyers: verify the Certificate of Conformity, Ex marking, special conditions, and exact configuration before purchase. Avoid costly compliance risks.
 How oxygen analysis helps prevent incomplete combustionOxygen analysis helps prevent incomplete combustion by optimizing air-to-fuel balance, reducing fuel waste, improving burner safety, and supporting emissions control.
 How to size an industrial gas system for stable peak demandIndustrial gas system sizing guide for stable peak demand. Learn how to assess flow, pressure drop, buffer storage, purity, redundancy, and commissioning for reliable production.
 How to choose a process sensor for high-temperature applicationsProcess sensor selection for high-temperature applications: compare thermal limits, materials, accuracy, installation, and maintenance to secure reliable control data.
 When does continuous analysis improve industrial process control?Continuous analysis improves industrial process control with timely composition data that supports faster decisions, higher quality, safer operations, and less waste.
 How to choose emission control systems for variable industrial loadsEmission Control solutions for variable industrial loads: learn how to match technology, controls, monitoring, and lifecycle costs for reliable compliance.
 How continuous emissions monitoring supports reliable emission reductionEmission Reduction relies on reliable continuous emissions monitoring. Discover how accurate data, calibration, and process insights support compliance and smarter control.
 When does it make sense to automate a production line?Production Line automation makes sense when processes are stable, measurable, and repeatable. Learn the key signals, risks, and ROI triggers before you invest.
 What accuracy should a monitoring device deliver in power quality applicationsMonitoring Device accuracy in power quality applications affects compliance, troubleshooting, and decision confidence. Learn what specs, standards, and installation factors truly matter.
 When does stack equipment make sense for small-scale production?Stack equipment can be a smart upgrade for small-scale production when space is tight and output is steady. Learn when it boosts efficiency—and when it adds costly complexity.




Search Categories
Search Categories
- Smart Meters & Power Quality
- Transformer Gas Analyzers
- BESS Thermal Runaway Detectors
- Energy, Power & Smart Grid Monitoring
- Optical Profilers & CMM
- Ultrasonic & X-Ray NDT
- Calibration Standards
- Precision Metrology & NDT
- Water Quality Analyzers
- CEMS & VOCs Monitors
- Price Trends
- Import & Export Updates
- Market Trends
- Industry News
- Industry Insights
Latest Article
- How to prevent false alarms in power plant instrumentationPower plant instrumentation guide: prevent false alarms with reliable signal checks, smarter alarm settings, mode-based control, and actionable operator responses.Posted by:
- How fixed gas detectors help prevent leaks in enclosed workspacesFixed gas detectors provide continuous leak monitoring in enclosed workspaces, enabling faster alarms, safer responses, and stronger protection for people and processes.Posted by:
- How industrial gas analysis helps detect process contamination earlyIndustrial Gas Analysis helps detect oxygen, moisture, and hydrocarbon contamination early, enabling faster fault isolation, safer operations, and stronger process control.Posted by:
Please give us a message
